Data Extraction
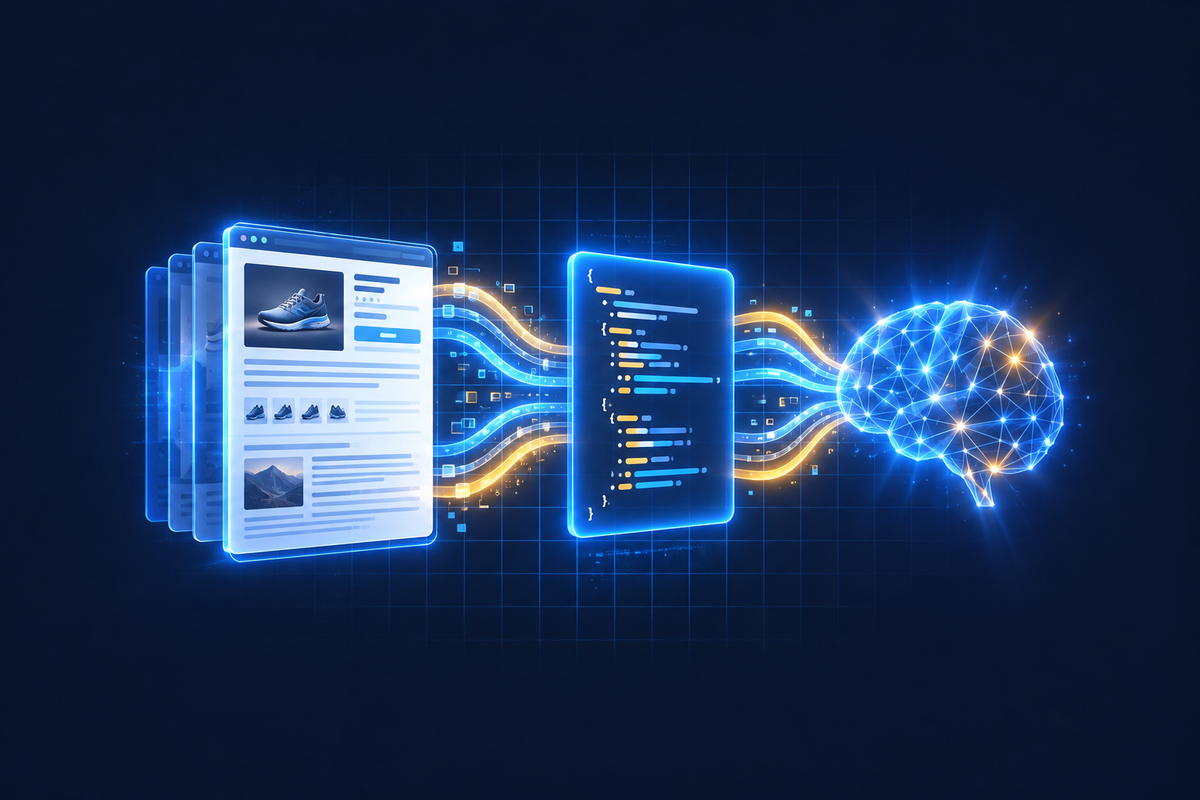
Field-Level JSON Extraction From Product Pages and Articles for LLM Reasoning
Define the schema first, then validate every extracted field.
Sana Ibrahim
· 9 min read
Define the schema first, then validate every extracted field.
Markdown wins for RAG, JSON for databases, and HTML comes last.
Test page access first, then output cleanliness, then cost at scale.
Raw HTML wastes tokens and hides content, so clean it first.
A staged pipeline turns messy scraped records into data AI can trust.
Web data breaks AI pipelines silently, so clean it before it reaches the model.
A completion webhook isn't enough, so test fetching, output, and errors.
Change detection belongs in scraping infrastructure, not in a cron-job wrapper.
Cloudflare judges whole sessions, so managed APIs win on upkeep.
Swap polling for webhooks while an adapter keeps agent inputs intact.
Multipliers and failure billing can double your scraping API bill beyond the advertised rate.
Three managed APIs cut anti-bot costs for startups without dedicated bypass engineers.